
Remove PDF Annotations
A PDF without page annotations. Delete page annotation arrays while retaining page text and vector content.
Open toolParse 1-based page numbers and ranges, then copy the selected pages into a new PDF. Unencrypted PDFs, up to 100 pages.
Enter the inputs, then select Extract selected pages.
Result will appear here
Parse 1-based page numbers and ranges, then copy the selected pages into a new PDF.
The tool processes the supplied input with browser APIs and bundled local libraries.
Supply supported input and review the result.
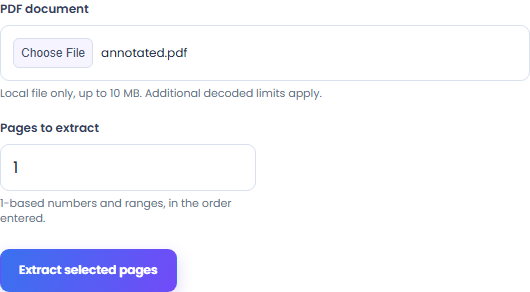
Choose PDF document. Processing reads the file in this browser.
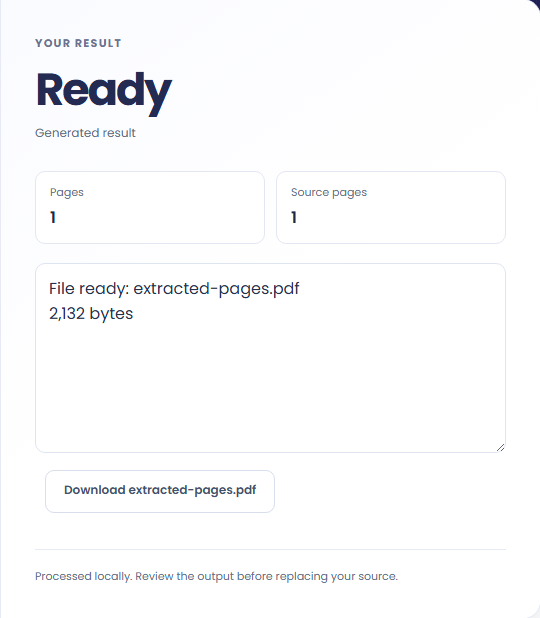
Save a PDF containing selected pages in your order. Check the download in its target application before replacing your source.
Enter a single page number for a standalone copy. Physical positions start at one.
Combine page numbers and ranges in the order needed. Repeated selections are rejected to avoid accidental duplicate pages.
The selected page content is copied into a new document. Document-level bookmarks and form structures are not transferred.
Review the format and conversion policy.
A PDF containing selected pages in your order. Unencrypted PDFs, up to 100 pages. Duplicate selections are rejected. Document-level forms, bookmarks and signatures are not preserved.
Keep the original while checking the saved output. The result reflects the input and settings you supplied.
Check these conditions before converting.
Unencrypted PDFs, up to 100 pages. Duplicate selections are rejected. Document-level forms, bookmarks and signatures are not preserved.
The page does not keep inputs or results after leaving. Keep the source and save the output you need.
A PDF without page annotations. Delete page annotation arrays while retaining page text and vector content.
Open tool
A PDF with revised visible page boundaries. Inset each current CropBox by the entered margins in PDF points.
Open tool
A PDF with flattened form fields or rasterized pages. Use pdf-lib form flattening or render all page appearances into an image-only PDF.
Open toolChoose another tool for your next calculation, conversion, or text task.
Write Markdown, update the rendered preview and download the Markdown or HTML when it is ready.
Open tool
Convert a modern .docx document to Markdown. Keep common text, headings, links and lists while leaving images, page layout and complex formatting for manual editing.
Open tool
Inspect quoted CSV cells in a readable table without uploading your data.
Open tool
Optimize self-contained SVG source with local SVGO processing. Choose decimal precision, download the smaller markup and compare its appearance with the original.
Open toolReview the supported output and save your result.
Answers about using PDF page extractor and understanding its results.
Save a PDF containing selected pages in your order. Unencrypted PDFs, up to 100 pages. Duplicate selections are rejected. Document-level forms, bookmarks and signatures are not preserved.
No. Processing uses browser APIs and bundled local libraries. The selected file or entered source is not sent to a conversion server. Save the result before leaving.