
DNA GC Content Calculator
Calculate GC percentage for DNA or RNA while separately counting unambiguous bases and IUPAC ambiguity symbols.
Open toolSee the frame and the incomplete trailing sequence alongside the counts. Provide Sequence alphabet, Reading frame, Raw coding sequence to compute results directly in your browser. Paste a raw sequence without FASTA headers. Whitespace is removed and letters are uppercased. Unsupported symbols are reported using 1-based positions in the cleaned sequence. At most 100,000 UTF-16 input units. Frames are 1, 2 and 3. DNA uses T, RNA uses U, with IUPAC ambiguity symbols retained. Codons containing ambiguous symbols are counted separately. This does not translate proteins or choose a genetic-code table.
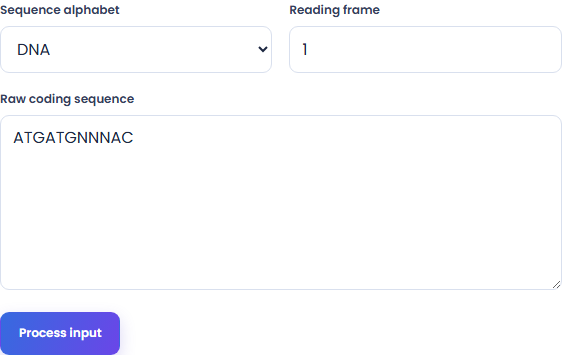
Enter the inputs, then select Process input.
Result will appear here
The Codon Usage Calculator evaluates Sequence alphabet, Reading frame, Raw coding sequence in client-side JavaScript using the deterministic rule below and updates the output panel immediately without uploading data to a server.
Offset = frame-1; each complete triplet contributes one count; frequency divides by all complete codons.
Paste a raw sequence without FASTA headers. Whitespace is removed and letters are uppercased. Unsupported symbols are reported using 1-based positions in the cleaned sequence. At most 100,000 UTF-16 input units. Frames are 1, 2 and 3. DNA uses T, RNA uses U, with IUPAC ambiguity symbols retained. Codons containing ambiguous symbols are counted separately. This does not translate proteins or choose a genetic-code table.
Review the input parameters, allowed value ranges, and worked reference cases for the Codon Usage Calculator below before running your calculation.
| Parameter / Scenario | Default / Sample Value | Rule or Allowed Range | Output / Usage Note |
|---|---|---|---|
| Input: Sequence alphabet | (User supplied) | Options: DNA, RNA | Required workspace parameter |
| Input: Reading frame | 1 | Range: 1 to 3 | Required workspace parameter |
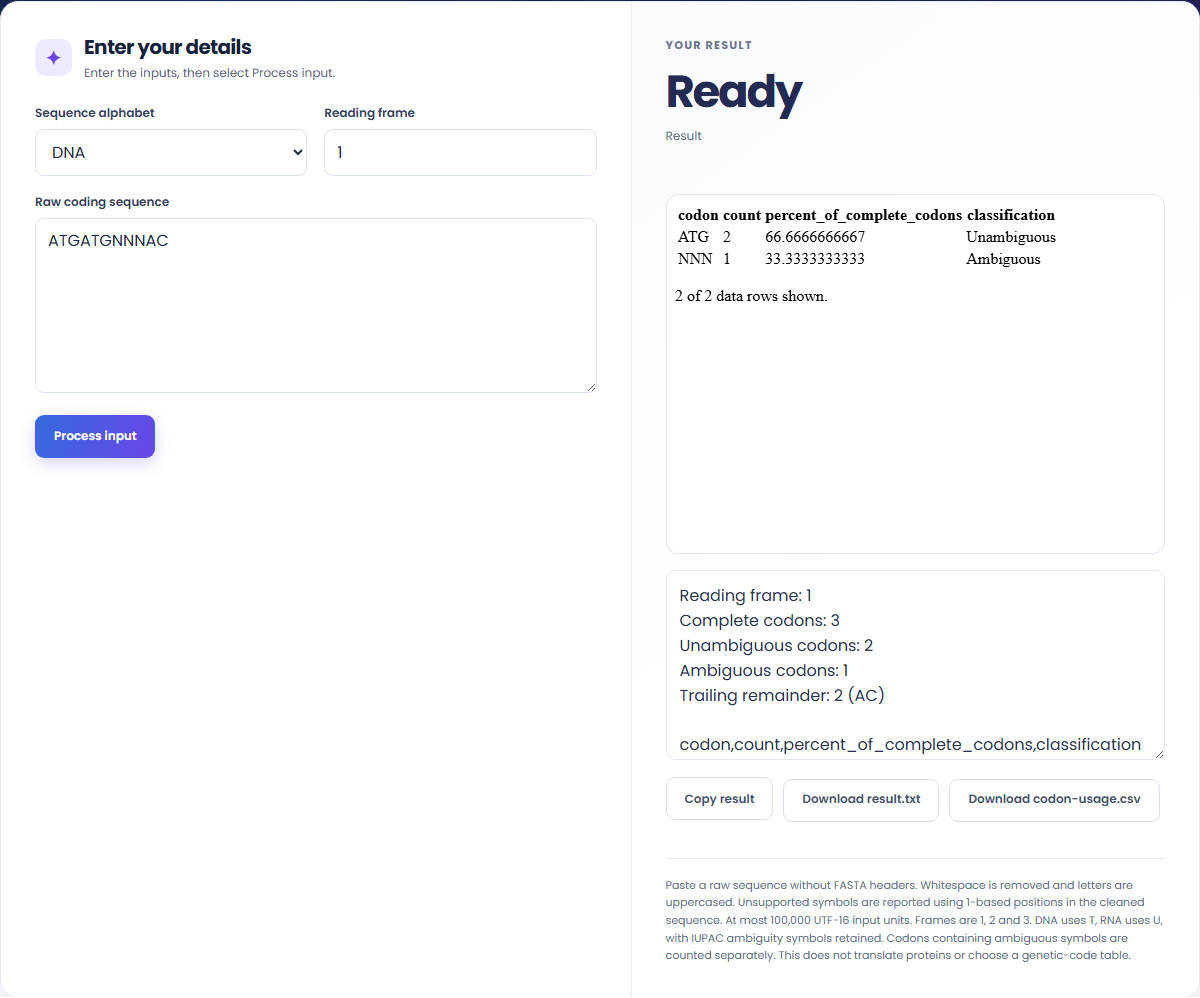
| Input: Raw coding sequence | ATGATGNNNAC | Input type: textarea | Required workspace parameter |
| Worked Case 1: Starting inputs | Preloaded / test values | Offset = frame-1; each complete triplet contributes one count; frequency divides by all complete codons | Sequence alphabet = DNA; Reading frame = 1; Raw coding sequence = ATGATGNNNAC |
| Worked Case 2: Comparison scenario (codon bias calculator) | Preloaded / test values | Offset = frame-1; each complete triplet contributes one count; frequency divides by all complete codons | Sequence alphabet = RNA; Reading frame = 2; Raw coding sequence = AAUGCCCU |
Follow these three steps to configure Sequence alphabet, Reading frame, Raw coding sequence, verify unit and boundary rules, and export your Codon Usage Calculator output.
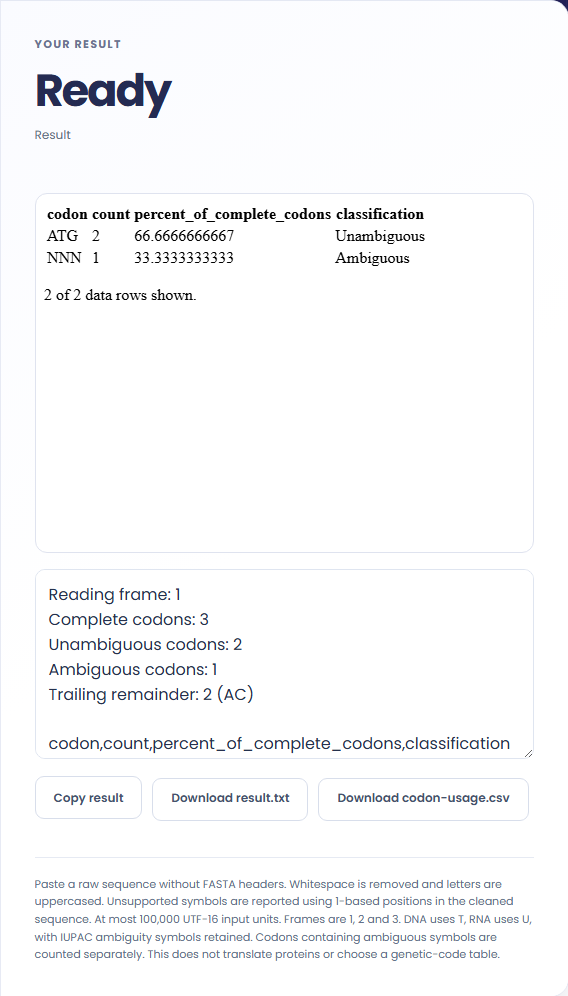
Read the result, then copy the text or save TXT. Use the separate format-download button for the actual file.
These concrete scenarios illustrate how the Codon Usage Calculator processes baseline inputs, comparison checks, and boundary constraints.
Sequence alphabet = DNA; Reading frame = 1; Raw coding sequence = ATGATGNNNAC
Sequence alphabet = RNA; Reading frame = 2; Raw coding sequence = AAUGCCCU
When solving for 'codon usage calculator', verify that Sequence alphabet, Reading frame, Raw coding sequence use consistent units and stay within the documented scope: Paste a raw sequence without FASTA headers. Whitespace is removed and letters are uppercased. Unsupported symbols are reported using 1-based positions in the cleaned sequence. At most 100,000 UTF-16 input units. Frames are 1, 2 and 3. DNA uses T, RNA uses U, with IUPAC ambiguity symbols retained. Codons containing ambiguous symbols are counted separately. This does not translate proteins or choose a genetic-code table.
The output panel reports the exact result derived from Sequence alphabet, Reading frame, Raw coding sequence alongside any unit or formatting notes.
Every calculation follows the rule: Offset = frame-1; each complete triplet contributes one count; frequency divides by all complete codons. Because JavaScript uses IEEE 754 double-precision floating-point arithmetic, numeric outputs display up to 12 significant digits where applicable.
Always cross-check the displayed result against the scope note (Paste a raw sequence without FASTA headers. Whitespace is removed and letters are uppercased. Unsupported symbols are reported using 1-based positions in the cleaned sequence. At most 100,000 UTF-16 input units. Frames are 1, 2 and 3. DNA uses T, RNA uses U, with IUPAC ambiguity symbols retained. Codons containing ambiguous symbols are counted separately. This does not translate proteins or choose a genetic-code table) before applying the value to production specifications, financial models, or lab records.
Review these boundary constraints and validation rules before relying on the Codon Usage Calculator output.
Operational scope: Paste a raw sequence without FASTA headers. Whitespace is removed and letters are uppercased. Unsupported symbols are reported using 1-based positions in the cleaned sequence. At most 100,000 UTF-16 input units. Frames are 1, 2 and 3. DNA uses T, RNA uses U, with IUPAC ambiguity symbols retained. Codons containing ambiguous symbols are counted separately. This does not translate proteins or choose a genetic-code table. Inputs that violate minimum/maximum bounds or required format rules are rejected with a clear diagnostic prompt.
Need an adjacent calculation in Math & Science? Use the related tools linked below to chain your workflow without leaving your browser.
Calculate GC percentage for DNA or RNA while separately counting unambiguous bases and IUPAC ambiguity symbols.
Open tool
Count protein-sequence residues, ambiguous symbols and percentages using an explicit accepted alphabet.
Open tool
Count unordered selections without repetition.
Open toolChoose another tool for your next calculation, conversion, or text task.
Answers about using Codon Usage Calculator and understanding its results.
The Codon Usage Calculator applies the rule: Offset = frame-1; each complete triplet contributes one count; frequency divides by all complete codons. Enter Sequence alphabet, Reading frame, Raw coding sequence into the workspace and the tool computes the exact output in your browser.
Yes. Provide Sequence alphabet, Reading frame, Raw coding sequence using the documented units and format shown in the quick reference table above. Preloaded default values let you test the workflow immediately.
Paste a raw sequence without FASTA headers. Whitespace is removed and letters are uppercased. Unsupported symbols are reported using 1-based positions in the cleaned sequence. At most 100,000 UTF-16 input units. Frames are 1, 2 and 3. DNA uses T, RNA uses U, with IUPAC ambiguity symbols retained. Codons containing ambiguous symbols are counted separately. This does not translate proteins or choose a genetic-code table. Confirm that your inputs fall within the allowed ranges before exporting the result.
Yes. All calculations for the Codon Usage Calculator execute 100% locally in your browser's JavaScript runtime. No inputs or results are uploaded to any external server.
Choose another tool for your next calculation, conversion, or text task.


